The Acceptance Bottleneck: Industrial Implications and Investment Criteria of the Super-agent Architecture Transition
1. About This Report
1.1 Why an internal engineering note became an industry paradigm
On October 31, 2026, the DeepSeek Harness team published an architecture note titled “Super-agent Design Exploration: Toward a More Autonomous Agent System.” Within hours of publication, Chinese technology media headlines were closely similar: “double-layer architecture,” “four features,” “five modules.”
What happened at the level of dissemination is clear: something that originally belonged to a team's internal engineering roadmap was read, within twenty-four hours, as the technical direction of the entire industry.
This reading did not come out of nowhere. The note did indeed articulate a change that a large number of teams had been sensing only vaguely — the Agent is moving from a single conversation to continuous presence. In the past, a user opened a window, asked a question, waited for an answer, and closed it; now the system continuously observes message streams, email, code reviews and execution results, and advances on its own when no one issues an instruction. This change is real, and it is not confined to software development scenarios.
The problem lies in the next step. When an internal note is disseminated as a paradigm, its boundaries are omitted along with it. The original text itself contains two sentences that happen to be exactly those boundaries.
The first appears at the beginning of the experimental section: “Because the experiments are based on synthetic loads and a simplified environment, some settings could be made more rigorous; the results below serve only as a preliminary reference.” The second appears in the conclusion: “We have not proposed an entirely new theory; rather, we have applied classic engineering ideas from computer systems to the construction of an Agent system.”
These two sentences describe the nature of the material quite accurately. It is an implementable engineering roadmap, not a technical conclusion that has been externally validated. Before using it as a basis for judgment, one more step is needed: first establish which parts can be checked, then judge how far those parts can be generalized.
What this report does is the second half of that step.
The technical verification has already been completed by this institute in the article “Super-agent Architecture: An Independent Recomputation.” That report compared the original data item by item and produced three conclusions that readers can recompute independently, together with a number of design judgments. This report does not repeat the derivation process; it takes those conclusions one step further and translates them into judgments that industry and investment can use. Readers do not need to read the technical recomputation first in order to finish this piece; when they need to check formulas and raw data, they can return to that article.
1.2 Three questions
For an architecture note, what engineers care about is whether it can be implemented as written. Analysts and investors care about three other questions.
The first is headroom. How far is this architecture from its capacity ceiling today? Headroom determines the rhythm of competition — ample headroom means this generation of architecture can still serve for two or three years, and the focus of competition is features; headroom running out means the infrastructure layer will soon be replaced wholesale, and the focus of competition is cost and scheduling. This judgment directly affects the time window for investment.
The second is the moat. Can its advantage over simpler approaches be replicated by cheaper means? If so, the architecture itself is not a barrier, and value will flow elsewhere; if not, the team that builds this architecture first will obtain a real structural advantage for a period. This judgment determines whether to invest in the architecture, or in what sits above or below it.
The third is the boundary. In which scenarios does it hold, and in which does it not? This judgment determines how vertical tracks are chosen. The same technology may be plug-and-play in software engineering and may not work at all in manufacturing sourcing; the reason is often not model capability but something else.
The three questions correspond respectively to Chapters 3, 4 and 7 of this report. The remaining chapters are supporting: Chapter 2 translates the technical claims into business propositions, Chapters 5 and 6 deal with two structural gaps in the original architecture, Chapters 8 and 9 discuss measurement and accountability, the two preconditions for procurement, Chapter 10 gives the judgment on value migration, Chapter 11 provides a due diligence checklist that can be used directly, Chapter 12 brings the conclusions back to manufacturing, and Chapters 13 and 14 set out the items still to be verified and the sources of method.
1.3 Evidence grading and discipline of judgment
This report follows the evidence grading of the technical recomputation; source grades are marked at the key computations and key judgments, so that readers can decide how far to trust them.
- E1: Stated explicitly in the original text and verifiable word for word.
- E2: Obtained by direct recomputation from data published in the original, with the formulas given in the main text.
- E3: An estimate by this institute, with the assumptions it relies on stated in the main text.
- E4: External public literature, with the source noted; the retrieval date is October 31, 2026.
The discipline of judgment has two rules. First, where the original does not disclose data, computed values are not used to complete the conclusions; points where the material is insufficient go into the list of items to be verified in Chapter 13, and the main text gives no substitute readings. Second, figures computed by this report and figures from the original are not mixed in the same concluding sentence; every computed value is labeled separately.
There is one further constraint that applies only to this report: it gives no market-size figures of any kind. The reason is methodological — the market boundary at the Agent architecture layer cannot currently be drawn; who counts inside and who counts outside can differ by an order of magnitude across definitions. Using a constructed total to support investment judgments is to hide uncertainty inside a number that looks certain. This report therefore discusses only structure: where value is generated, where it migrates, and who captures it.
1.4 Conclusions first
The judgments of the following chapters, compressed into five points.
First, the engineering headroom of this architecture is seven percent, which is not on the same order as the original’s judgment that it “has still not reached the throughput bottleneck of a single Router.” Recomputing from the arrival rate, batch size and per-request latency that the original itself publishes, the Router's utilization at about 40 Triggers per minute is approximately 0.93. The original's judgment is “has still not reached the throughput bottleneck of a single Router”; what the data supports is that it is already running right up against the bottleneck. This means that the scaling problem for the continuous-presence generation of systems will arrive earlier than the original expects.
Second, its core advantage has not been shown to come from the architecture. The original's experiments lack one key control: a single session with forced delegation. Without that control, it is impossible to distinguish whether the benefit comes from the two-layer structure or from removing the model's discretion over delegation. The latter costs a few lines of code to implement. Until this control is run, the architecture's premium cannot be stated clearly.
Third, the original architecture is missing a module, and the omission is remarkably consistent. All five modules answer how to begin and how to continue; none answers how to end. Long-running operation produces five classes of residue; most of them do not produce errors but mainly produce costs, so they are not caught by alerting — they appear as an inexplicable decline in efficiency.
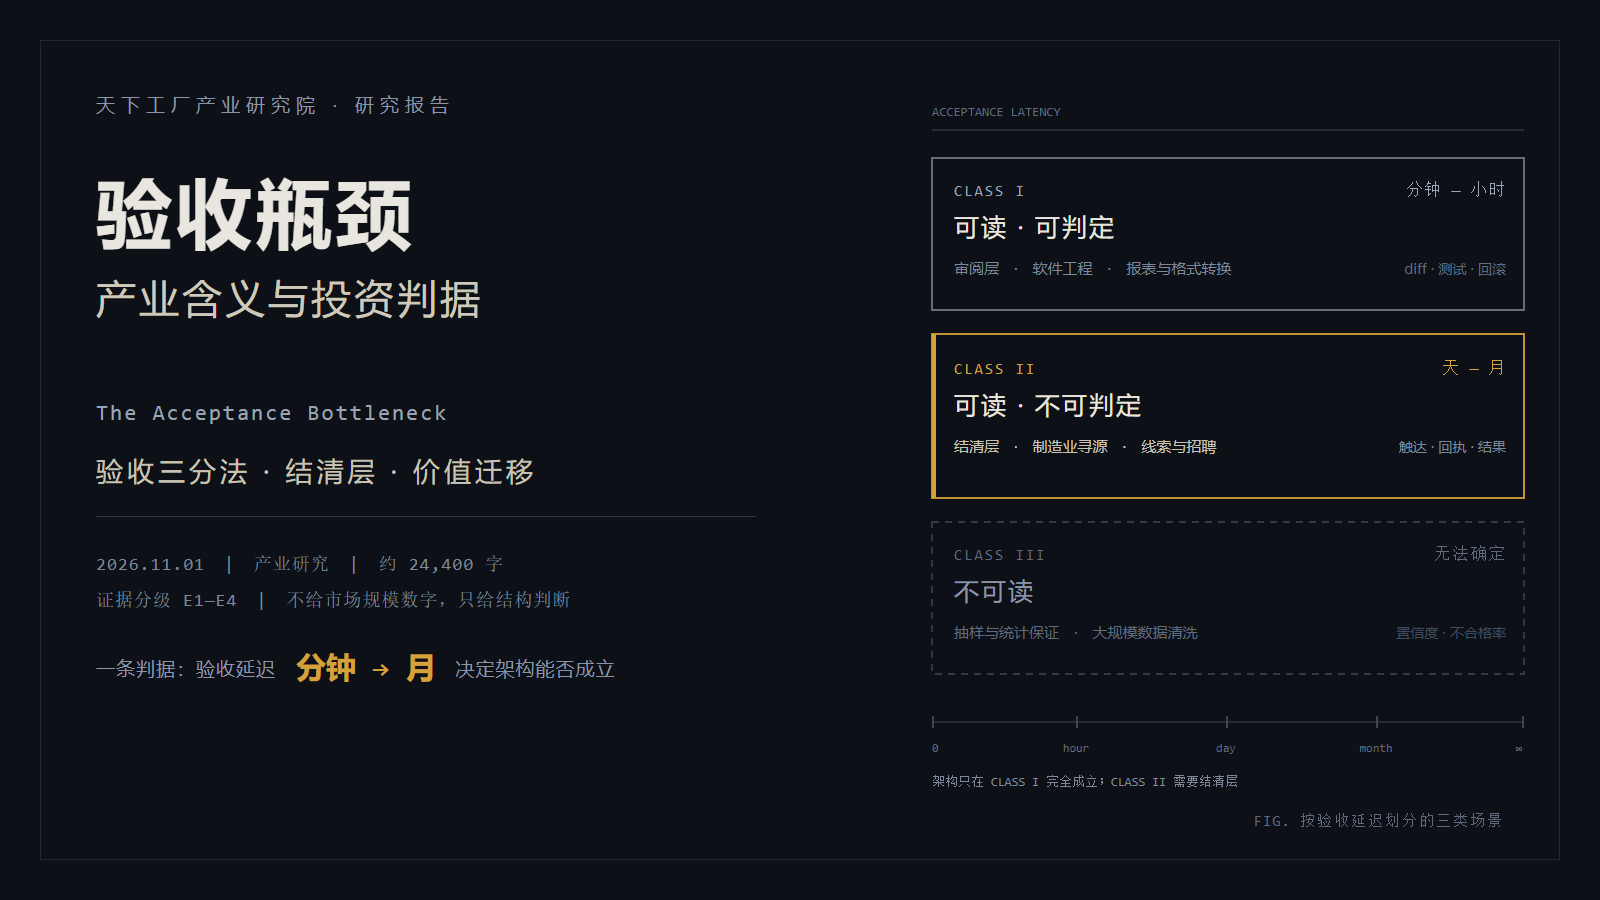
Fourth, this architecture holds completely in only one of three classes of scenario. Classified by acceptance latency, software engineering is readable and decidable, and the original architecture holds; manufacturing sourcing is readable but undecidable, and what it needs is a settlement layer rather than a review layer; the third class, unreadable scenarios, the current architecture cannot carry. This criterion is a better predictor of whether a vertical Agent can be put into use than model capability is.
Fifth, value will shift from who can generate to who holds the facts that acceptance requires. The cost of generation capability is still falling rapidly, while acceptance capability is constrained by human judgment and organizational authorization; the gap between the two curves is widening. Whoever holds the part of the facts that acceptance requires — receipts, results, subsequent behavior — occupies the position on this chain that is hardest to replace.
2. Translating the architecture claims into business propositions
2.1 The seven propositions in the original
To judge the business meaning of an architecture note, one must first write its claims as sentences that can be judged true or false. The original's argument can be broken into seven items.
- P1: The ceiling on single tasks depends on model capability; the ceiling on multiple tasks depends on human attention. As execution-side dependence on people declines, the bottleneck limiting further efficiency gains is shifting toward human attention.
- P2: The session should be an implementation detail of the system, not a cognitive burden for the user.
- P3: A two-layer architecture can obtain both cross-channel continuity and multi-task throughput.
- P4: Event-driven design can move the Agent from passive execution to active response.
- P5: Separating computation, state and environment can achieve persistent online presence across devices.
- P6: An external Watchdog can achieve exception self-healing during long-running operation.
- P7: The propositions above hold under real workloads.
This decomposition is not excessive. The original itself limits the scope of P7 at the beginning of its experimental section — “the results below serve only as a preliminary reference.” What this report does is apply that limitation to each proposition in turn, to see which fall inside the scope and which fall outside.
2.2 From technical propositions to business propositions: three hurdles
For a technical claim to become a business proposition capable of supporting a valuation, it must clear three hurdles. These three hurdles are not technical, but they determine whether the technology can become a business.
Reproducible. Can the same input reliably produce the same output? This rule determines whether the product can be delivered. Succeeding once in a demonstration environment and succeeding a thousand times in a thousand customers' own environments are two different things. The original itself admits that the experimental environment was simplified: coding work was replaced by a tool that only consumes time, and message intervals and work durations were scaled to one quarter. These two simplifications are reasonable for measuring scheduling capability, but insufficient for measuring reliability.
Settleable. Can the cost of a service be attributed to a specific output? This rule determines whether the product can be priced. The cost structure of an Agent system differs from that of the previous generation of software: it is not a fixed license, but a continuous quantity that varies with task length, context size and number of retries. Without a mechanism that attributes cost to output, pricing can only rely on estimates; estimates will be challenged by customers, and challenges will lengthen the procurement cycle.
Attributable. Can an action that escapes the sandbox be traced to a subject that bears responsibility? This rule determines whether the product can enter the enterprise. Internal enterprise tools can lack a responsible subject, because organizational relationships solve that problem naturally; once a service is offered externally, every action of sending a message, committing code or issuing a quote requires a subject that can be held to account.
Of the three hurdles, the first is an engineering problem, the second a measurement problem, and the third a governance problem. The original's five modules mainly address the first half of the first hurdle and barely touch the latter two. This is not a defect — an architecture note internal to a team does not, by nature, have to carry all the conditions of external commercialization. But if readers take it as a paradigm, they will inherit the gaps in all three hurdles along with it.
2.3 The evidential strength of the five modules is not the same
The original proposes four foundational features and supports them with five modules. Setting the evidence for each module side by side, the differences in coverage are quite obvious.
| Module | Core mechanism | Corresponding feature | Evidence given in the original | Extent of experimental coverage |
|---|---|---|---|---|
| Two-layer architecture | Resident Router plus isolated Worker | Continuity, efficiency | 7.1 completion-time comparison, 7.2 batch stress test | Partially covered |
| Event-driven | Trigger, Thread, subscription pass-through, chain of recall, speculative execution | Proactivity | The token comparison for “removing pass-through” in 7.1 | Covers pass-through only |
| Human-oriented interaction | Asynchronous ReAct Loop, multi-channel output specification | Continuity, efficiency | No experiment; states “already implemented in DeepSeek Harness but not yet enabled by default” | Not covered |
| Separation of computation from state and environment | Stateless cloud-side Loop plus device-side daemon | Persistence | No experiment | Not covered |
| Watchdog | An independent session driven by an external timer | Persistence | No experiment | Not covered |
Not covered does not mean untrue. The capabilities described in the fifth and sixth sections could well already work in engineering terms; they simply have not been published in experimental form. What this report points out is something else: the persuasiveness of this note is unevenly distributed.
What readers remember most easily are the p50 and p95 in Section 7.1 — 12.4 minutes and 15.7 minutes. The conclusion these two figures support comes down to one sentence: the two-layer architecture shortens task completion time under synthetic loads. They do not support continuous online presence, exception self-healing and cross-device switching, the three capabilities that are easier to impress people with. When the media list these four features alongside the five modules, the message readers receive is that all five are equally certain, when in fact their evidential strength differs by an order of magnitude.
For investment judgments, this distinction is very practical. If a team claims to have built a Super-agent architecture, the follow-up question is: which modules has it built, and which of them have control data. What most teams can currently produce is part of a two-layer architecture plus part of event filtering; the rest is design documentation.
2.4 A concept that was merged
P1 is the starting point of the whole piece. The sentence reads like a law, but is in fact a description of the state of current designs.
The premise on which it holds is that a person must simultaneously bear two things — tracking task status and bearing the consequences of the task.
The scalability of these two things is completely different.
Tracking status can be outsourced. As long as there are reliable records, retrieval and reminders, the number of tasks one person tracks can rise from five to fifty. This is exactly what CRM systems do, and what project management software does. Their value lies precisely in moving remembering out of the human brain.
Bearing consequences cannot be outsourced. To accept an output means that the acceptor is responsible for the correctness of that output. The capacity for responsibility is constrained by professional judgment and organizational authorization, not by interface design. A procurement manager can follow the progress of twenty quotations at once, but the ones that actually require his signature confirming “this supplier can be ordered from” may be only five a day — not because he cannot remember them, but because every signature consumes his professional judgment and career risk.
The empirical observation the original uses to support P1 is “a person can typically follow only 3 to 5 active Sessions at the same time.” No sample, measurement method or population is given for this figure; it can only be treated as an empirical value. Its mechanism may correspond to three different constraints: working memory capacity, the cost of resuming after interruption, and the capacity to bear consequences. The first two can be reduced through architecture and interaction; the third cannot.
The original lumps the three together as human attention, and thereby gains a convenience in argument: as long as it shows that tracking costs have fallen, it is as if it has shown that the attention bottleneck has been eased.
This report holds that this merging conceals the real problem. Once the two things are separated, a different conclusion follows: the Super-agent relieves the tracking bottleneck, not the acceptance bottleneck. Moreover, as the tracking bottleneck is relieved, the acceptance bottleneck will be exposed faster — because the output awaiting acceptance produced per unit of time increases.
This inference recurs in later chapters. The settlement gap in Chapter 6, the three-class acceptance taxonomy in Chapter 7, and the M3 and M4 metrics in Chapter 8 are all extensions of this line.
2.5 The result of translating the business propositions
Running the seven technical propositions through the three hurdles yields a comparison table.
| Original proposition | Business meaning | Current status |
|---|---|---|
| P1 Attention is the bottleneck | The selling point is that one person can advance more tasks | Holds only for the tracking part; the acceptance part is unsolved |
| P2 Session is an implementation detail | The product form can be freed from the chat window | The direction holds; the replacement form is undetermined |
| P3 The two-layer architecture delivers both continuity and throughput | Continuity and efficiency can be sold together in one system | Supported by experiment; lacks the key control |
| P4 Event-driven design brings proactivity | Can change from a tool into a colleague | Only pass-through has data |
| P5 Compute-storage separation brings persistent online presence | Can serve continuously across devices and scenarios | No experiment; engineering-credible |
| P6 Watchdog brings self-healing | Can reduce operations headcount | No experiment; engineering-credible |
| P7 Holds under real workloads | Can be delivered directly to enterprises | The original itself states it is a preliminary reference |
The most important thing to read in this table is the last column. Of the seven propositions, only one and a half have experimental support; the rest are design judgments or engineering common sense. This does not affect the value of the architecture — the value of a roadmap lies precisely in pointing out a direction — but it determines what kind of investment judgment can be made at the current stage.
What can be done is a directional judgment: the direction of continuous presence is right, and someone will make it work. What cannot be done is a timing judgment: one cannot infer from this note that large-scale rollout will happen next year, because of the three conditions that rollout requires — reproducibility, settleability and attributability — the original addresses none.
These three conditions are also precisely the coordinates to which later chapters of this report repeatedly return.
3. Recomputation One: Seven Percent of Headroom Remains
3.1 Three Numbers Are Enough
In order to explain the batching mechanism at the Router layer, Section 7.2 of the original article disclosed three quantities: the arrival rate of Triggers that need a decision, the average batch size, and the time consumed by a single request. These three quantities are enough to compute the most critical metric of a queueing system—utilization.
The values given in the original article are: the arrival rate rises from about 1 per minute to about 40 per minute; the average batch size rises from 1.0 to 2.8; the time consumed by a single request increases from 2.5 seconds to 3.9 seconds. In addition, the original article also gives the “inference time amortized per single decision”, which falls from 6.4 seconds to 1.6 seconds.
A note on definitions is needed first. The original article does not define these two quantities. Taken literally, “inference time amortized per single decision” equals the time consumed by a single request divided by the batch size; at a batch size of 1 the two should then be equal, yet the original reports 2.5 seconds and 6.4 seconds, which are not equal. This report therefore uses only “time consumed by a single request” for the utilization recomputation, and cites “inference time amortized per single decision” only as a directional reference.
3.2 How Utilization Is Calculated
For a system that serves in batches, the basic formula for utilization is:
ρ = (λ / b) × S
Here λ is the number of Triggers arriving per second, b is the average batch size, and S is the time consumed by a single service (in seconds). The intuitive reading is: the system must process λ/b batches per second, each batch occupies the server for S seconds, and multiplying the two gives the proportion of time the server is occupied.
Substituting the original data. The arrival rate is 40 per minute, that is, λ = 40/60 ≈ 0.667 per second; b = 2.8; S = 3.9 seconds.
ρ = (0.667 / 2.8) × 3.9 ≈ 0.93
When the arrival rate is 1 per minute, λ = 1/60 ≈ 0.0167; b = 1.0; S = 2.5 seconds.
ρ = (0.0167 / 1.0) × 2.5 ≈ 0.042
That is to say, over the entire stress-test interval, the utilization of the Router rises from about 4% to about 93%.
This is inconsistent with the judgment in the original article. The original article's exact words are “Even if removing pass-through increases the Router's peak load, the throughput bottleneck of a single Router has still not been touched”, and the sentence that follows immediately is “Therefore, at our current team size, there is no need to prematurely shard the Router layer horizontally and sacrifice the continuity of the global context”.
Reaching the bottleneck has a relatively definite meaning in engineering: utilization approaches 1, and queueing time rises nonlinearly with load. 0.93 already falls inside that range. The headroom is seven percent, which is inconsistent with the original's judgment that it “has still not reached the throughput bottleneck of a single Router”.
One point should be stated fairly: the upper limit of this stress test is 40 Triggers per minute, and the original article does not claim that 40 is the limit of the system. What the original article says is that within this interval the batching mechanism is effective. That statement in itself is not wrong. The problem is that the move from being effective within this interval to not having touched the bottleneck omits a step—and at the point of 40 per minute, utilization has already reached 0.93; push higher, and the gains from batching will be eaten by queueing delay.
3.3 Where the Batch Size of 2.8 Comes From
There is another point that deserves more attention.
By definition, if the Triggers that newly arrive during one service period of a system are merged into the next call, then the natural value of the batch size equals the number of Triggers newly arriving during one service period, that is, λ × S.
Substituting the case of 40 per minute: λ × S = 0.667 × 3.9 ≈ 2.60.
The average batch size measured in the original article is 2.8.
The two are almost equal.
The implication of this coincidence is that the batching observed in the original article cannot be distinguished, in the data, from the backlog that an ordinary queueing system naturally forms under load. The original article gives no reading that would distinguish a batching window from queue backlog, such as the number of delayed schedules or the distribution of batch formation times. On the available data, the least forced explanation is that during the period when the previous call has not yet returned, newly arriving Triggers queue up, and the next call carries them along together.
This distinction matters for the interpretation of the metric.
If batching is an active policy, then the gains can be attributed to design, and other teams that copy it can obtain them as well. If batching is merely natural backlog, then the gains require no design, and any single-threaded server will produce the same curve once load rises. The former is replicable engineering experience; the latter is an inevitable result of queueing theory.
For investment judgment, this distinction determines one thing: the “inference time amortized per single decision falling from 6.4 seconds to 1.6 seconds” shown in Section 7.2 of the original article cannot be read as meaning that this architecture has a special throughput optimization. The more accurate reading is that, after the load rises, fixed overhead is amortized.
This does not affect the usability of the system. What it affects is transferability—a team that follows this description to implement an active batching scheduler may find that the gains are far smaller than expected, because the gains measured in the original article did not come from the scheduler in the first place.
3.4 Implications for the Pace of Industry Competition
Combining the two points above yields a judgment about the time window.
First, the engineering headroom of this generation of continuously present architecture is seven percent, which is not on the same order as the room the public narrative implies. The narrative of the original article gives the impression that a single Router still has a great deal of room, and that the capacity expansion problem can be deferred. The recomputation shows that at the original article's own stress-test ceiling, only seven percent of headroom remains. This means that as team size grows and event density rises, the horizontal sharding problem will become urgent at an earlier point than expected.
Second, horizontal sharding directly damages the most valuable part of this architecture. The original article itself puts it clearly: the finer the sharding granularity, the higher the concurrent throughput at the Router layer, but the lower the continuity of memory and context between shards; “before the global memory problem is solved, this trade-off will always exist”. In other words, this architecture currently sits in a dilemma—without sharding, throughput hits its ceiling; with sharding, continuity is discounted. And continuity is precisely the selling point that distinguishes it from an ordinary Agent Team.
Third, this dilemma will reshape the focus of competition. From 2025 to the first half of 2026, the competitive focus of Agent products was capability: whether it can complete tasks, whether it can call tools, whether it can reason over multiple steps. As capabilities level off and architectures converge, the focus will shift to scheduling efficiency and unit cost. Whoever can complete the same task with fewer tokens, a shorter queue, and more stable latency will be the one that survives at the same price.
This judgment has a testable corollary: if the headroom of this architecture really is only seven percent, then over the period that follows, the center of public discussion should shift from how many modules the architecture has to what the cost per unit of output is. Observing when this shift happens is more informative than observing how many new concepts have appeared.
3.5 Three Leading Indicators That Can Be Watched Continuously
For observers who do not have direct access to the system, the following three indicators can be inferred indirectly from public materials at very low cost.
First, the slope of the time consumed by a single request as the arrival rate rises. If the time consumed grows more slowly than the batch size, batching is still effective and the headroom is still there; if the two grow at the same rate or even faster, fixed overhead can no longer be spread and the system is close to its ceiling. The original data are: the batch size grows to 2.8 times, and the time consumed grows to 1.56 times. This ratio measures amortization efficiency and does not change the headroom measured in Section 3.2; it describes how latency grows as load continues to rise, and that change appears before a failure does.
Second, the ratio of batch size to natural arrival volume. That is, b divided by λS. If this ratio is close to 1, the so-called batching is just queueing; if it is clearly greater than 1, the system is genuinely accumulating batches. This indicator requires no internal data; it can be computed with only three public numbers—arrival rate, batch size, and service time consumed.
Third, the token consumption per unit of output. The original article reports that the cache-read tokens of a single Super-agent experiment were 23.23 million, and the experiment contained about 20 work requests; converted on this basis, each work request comes to about 1.16 million cache-read tokens (E2, computed by this institute). This order of magnitude shows that the cost center of this architecture is not executing tasks but repeatedly reading context. When model unit prices fall, this cost falls with them; when the context size rises, it rises faster. Which of the two forces is stronger determines the economics of this architecture.
4. Recomputation Two: The Experiment Does Not Measure What It Wants to Prove
4.1 The Distance Between Claim and Measurement
The starting point of the original article is P1: the upper limit of multitasking depends on human attention. The architectural goal derived from it should therefore be to raise the number of tasks a person can advance per unit of time. This is a human throughput indicator.
What Section 7.1 of the original article measures, however, is “task completion time”: the time consumed from a work request to the result message, taking p50 and p95. This is a single-task latency indicator.
The two are not in a monotonic relationship.
A system can perfectly well lower single-task latency while lowering human throughput. The reason is direct: if it produces more small outputs that require human acceptance, the human switching cost rises, and the number of things actually settled per unit of time falls instead. Conversely, a system can also raise single-task latency while raising human throughput—by accumulating several tasks and accepting them together in one batch; latency rises, and the number of tasks completed per unit of time increases.
Therefore, using the ranking of single-task latency to support a conclusion about the attention bottleneck is a matter of construct validity: the variable measured is not the variable the claim is about.
This is not nitpicking. Section 4.1 of the original article itself proposes full-duplex interaction, and its purpose is stated clearly—“to allow the session to accept new instructions at any time without waiting for the previous command or task to complete”. This is a throughput claim. If the experiment measures only latency, then the entire asynchronous ReAct Loop module is empty as far as the experiment is concerned.
The same misalignment appears in another simplification of the experiment. Section 7.1 of the original article replaces the coding work with a tool that only consumes time; this simplification is reasonable in itself, and it lets the experiment focus on measuring scheduling and collaboration capability. But it also means that the dimension of output quality does not exist in the experiment. In a real experiment, output quality is precisely the main source of acceptance cost—a plan that is poorly written but fast will make the acceptor spend more time.
4.2 The Missing Control
Section 7.1 compares four configurations: the complete Super-agent, the Super-agent with pass-through removed, a single session plus sub-agent tool under a neutral prompt, and a single session plus sub-agent tool under a pro-delegation prompt.
These four configurations omit one: the forced-delegation single session.
Forced delegation means that the harness unconditionally hands each work request to a new sub-agent, not leaving it to the model's judgment. This configuration differs from the pro-delegation prompt in only one implementation detail—replacing the prompt that suggests delegation with code that requires delegation; everything else is identical.
Why is this control critical? Because the original article's own data already hint at its importance.
Under the neutral prompt, the model did not call a sub-agent once in five runs; all the work was carried out in the main session, constantly interrupted by new messages, and p95 reached 29.5 minutes. After switching to the pro-delegation prompt, four of the five runs delegated, and completion time shortened somewhat but remained slower than the Super-agent; in the remaining run, the model judged the work to be “very small” and chose to execute it itself, forming the purple long tail that the original article describes.
This description shows that this instance of the purple long tail can be attributed to the model's misjudgment of its own workload: it judges the work to be “very small” and does it itself; if the judgment is wrong, the whole pipeline is blocked. But after four delegations it was still slower than the Super-agent, which means the loss does not come from misjudgment alone. Whether structural factors also play a part requires the forced-delegation control to determine.
If the problem lies in judgment, then the solution can be not letting it judge.
4.3 Two Possible Results, Two Different Valuation Implications
If the forced-delegation control is added, two results are possible, and their commercial implications are completely different.
The first: forced delegation is roughly on par with the two-layer architecture.
This means that the main value of the two-layer architecture lies not in the two layers but in removing the model's discretion over delegation. The source of the gains is: turning the decision of whether to divide the work from a probabilistic judgment into a deterministic rule.
If this conclusion holds, the impact is large. Its implementation cost is a few lines of harness code; it requires no Router, no subscription pass-through, no chain of recall, no Watchdog. For the vast majority of teams, this is a far more cost-effective choice than the entire architecture.
The investment implication is that the premium of the architecture layer is substantially compressed, and value shifts downstream to scenarios and data. A differentiation of only a few lines of code cannot support the valuation of a layer of infrastructure.
The second: forced delegation still lags clearly behind.
Only this would show that the two-layer structure itself brings gains. There are several possible mechanisms: the output convergence brought about by the Worker not replying directly to the outside; the reduction in Router load brought about by subscription pass-through; the improvement in single-task quality brought about by context isolation. The original article gives evidence for one of them in Section 7.1—after removing pass-through, completion time is essentially unchanged, but the number of Router decisions increases by about 30%, and total cache-read tokens rise from 23.23 million to 31.77 million, an increase of about 37%. This is a clean piece of evidence that subscription pass-through is effective.
Under this result, the value of the architecture layer holds: the team that built this system first has a structural advantage, and companies that pursue engineering optimization around Router, subscriptions, and recall have investment value.
The original article did not run this control, so it cannot distinguish between the two cases. The p50 and p95 differences it gives are simultaneously compatible with two explanations: that the architecture is superior, and that forcing is more effective than suggesting.
4.4 The Moat May Be Only a Few Lines of Code Deep
This is the point this report considers most useful for investment judgment.
In technical evaluation, a common error is to equate being effective with this configuration being effective. The original article's experiment does prove that the complete Super-agent is faster than a single session. But it does not prove what the cause of the speed is.
Judging from the shape of the data, the least effortful explanation is a prompt effect: under the neutral prompt the model does not delegate; under the pro-delegation prompt the model delegates four times, and performance improves accordingly. Along this chain, the variable that does the work is whether the model is allowed to decide the division of labor itself, not how many layers the system has.
If this explanation holds, then the real innovation of this architecture is that it turns a matter requiring model judgment into a rule that requires no judgment. This is indeed a good design—replacing an uncertain judgment with a deterministic mechanism is a classic technique in systems engineering. But the depth of its moat does not match the complexity with which it has been described.
For an investor, this judgment can be turned into a specific question: of this company's technical advantage, how much is that we thought of this structure, and how much is that we tuned this structure until it ran? The former can be copied; the latter requires time and data. The two should be valued separately.
4.5 A Usable Criterion
From this, a criterion can be derived: look at whether an Agent company has run control experiments.
Ask three specific questions. First, have you measured forced delegation or an equivalent simplified configuration? Second, if so, how much does the result differ? Third, if not, how do you know the gains come from the architecture rather than from the prompt?
A company that has clear answers to the first two questions shows that its technical judgment is built on experiments it has run itself. A company that cannot answer the third question is very likely using an unverified structure to explain a phenomenon that can be explained elsewhere.
This criterion is far more useful than looking at architecture diagrams. The more beautiful the architecture diagram, the more it needs evidential support; between a technical material that has only five module diagrams and no control experiment, and a technical material of only two pages with a clean ablation study, the latter is more worthy of belief.
5. Structural Flaw One: Routing and Memory Are Bound Together
5.1 The Two Responsibilities Extend in Opposite Directions
The original article defines the Router layer as a resident global routing layer, and explicitly states its three identities: the global sequence point, the coordinator, and the memory.
The original article also recognizes the risk in this node, and writes immediately afterward: “To avoid this global node becoming a performance bottleneck for the system, the Router layer by design does not directly execute specific tasks; it is responsible only for human interaction and task dispatch, and may even be configured without Bash tools.”
This handling is correct: move the heavy work elsewhere and let the central node make only lightweight judgments. But it handles only half of the problem. The load the Router bears is not only that of executing tasks; it also carries that of remembering everything.
The problem is that the requirements these two responsibilities place on context point in opposite directions.
Routing wants context to be short. The input to a single routing decision essentially requires only three things: what this event is, whom it should go to, and which tasks are currently running in the system. The more concise the information, the faster and more accurate the judgment. The original article's own cost data confirm this: a single experiment consumed 23.23 million cache-read tokens, which, apportioned over 20 work requests, comes to about 1.16 million per request. This magnitude shows that the main part of the cost is not thinking but repeated reading.
Memory wants context to be long. Global memory must answer questions such as why that task changed its approach three months ago; the information required is the complete history and the reasons for decisions. The shorter the context, the less reliable the recall.
Putting the two into the same session yields an inevitable result: every routing decision pays for the entire memory.
This is not to say that the design is wrong. When the team is small and the task history is short, a single resident session doing both things is the simplest choice in engineering, and it is indeed adequate. The problem lies in scalability—once memory grows to a certain scale, the cost of routing rises linearly with the memory, while the complexity of routing itself does not change.
5.2 Three Secondary Consequences
This coupling also brings three consequences, all of which manifest in long-term operation, and all of which affect valuation.
The first is availability. The persistence of global memory is bound to the survival of a single session. Session state is already stored in a database as described in Section 5.1, so context can be recovered after a restart; what is unclear is whether global memory can be rebuilt from that persisted state, because the original article does not describe that rebuild path. The Watchdog can restart the session, but whether the restarted session is still the same global memory is not explained in the original article. For enterprise customers, this is a question that will be written into an SLA: if the boundary of core memory depends on the survival of a process, the availability of this system on critical processes cannot be committed.
The second is replaceability. To change the model the Router uses, one must migrate the memory at the same time. This binds model upgrades and architecture upgrades together, making it difficult for a team to perform incremental replacement. This consequence is not yet visible at the current stage, because models are replaced several generations a year and the architecture is changing along with them anyway. But once the system enters a stable operating period, model upgrades will become a high-frequency matter—each new generation of models differs in price and capability, and not changing means falling behind. At that point, having to migrate memory in order to change models will become a real operating cost.
The third is evaluability. To compare the merits of two Router strategies, each must maintain its own memory, or the comparison does not hold; yet once each maintains its own, the two memories diverge again. The cost of evaluation is therefore far higher than for a stateless component. This item does the most damage to teams that iterate on a product: it means that every A/B test requires duplicating an entire history, and the test cycle is lengthened.
5.3 The Sequence Point Should Be a Log Sequence Number
The original article uses the term “Sequence Point”; this report calls it the sequence point below. The term comes from database and logging systems and means a position in the global order. In this context, the function of the sequence point is to provide a unified timeline for cross-task events, so that judgments of what occurred before, what occurred after, and what was concurrent are determinate.
In a logging system, a sequence point is a monotonically increasing number, usually called a log sequence number (LSN). It is a value, not a process. A process can crash, restart, be replaced, or scale horizontally, while the log sequence number does not change; any component, so long as it remembers which number it has processed up to, can resume from the correct position after a restart.
By placing the sequence point in a resident session, the original article hands the responsibility of a value to a process. This brings two unnecessary constraints: the availability of the global order depends on the survival of that process; the integrity of global memory depends on the context length of that process.
A more stable structure separates the three.
The event log is the sole authority. All events entering the system, all decisions made, and all external actions are written in order to an append-only log. The log cannot be modified, only appended to, so it is inherently complete, replayable, and auditable.
A session is only a working set. Each session remembers which sequence number it has processed up to, and loads the segment of context it needs. A session can be destroyed, rebuilt, or migrated to another machine; continuity is guaranteed by the log.
Memory is a materialized view over the log. Global memory is not an entity that needs to be protected, but a result computed on demand from the log. When the answer to why that task changed its approach three months ago is needed, it is queried from the log rather than rummaged through in the context of a session. Query results can be cached; when the cache expires they are recomputed, and recomputation does not change the facts.
This structure has been validated in the database field for decades; it is not a new invention. Its value when used here is that it turns memory from a state that must be carefully protected into a derived result that can be rebuilt at any time. This change directly resolves the three consequences above—availability is guaranteed by the log, replaceability by the interface, and evaluability by replay.
Section 5.2 of the original article cites the “decoupling the brain from the hands” proposed by Anthropic, and explains that this line of thought “likewise keeps the harness stateless and stores session logs outside the harness.” This sentence shows that the original article does recognize the value of statelessness. The problem is that it applies this recognition on the Worker side, while the Router side still places global memory in the session.
So the problem here is not that the original article failed to think of statelessness, but that statelessness is only half done. A half-stateless system is not much better in scalability than a fully stateful one—because the bottleneck concentrates on the one node that has not been decoupled.
5.4 A New Form of Vendor Lock-in
For investors, this structural flaw has a direct commercial consequence: it creates a new form of lock-in.
Over the past decade, lock-in in enterprise software has mainly occurred at the data layer: the data sits in the vendor's database, migration costs are high, and so customers do not leave. In the SaaS era this problem was partly solved, because most SaaS products provide data export.
Agent systems bring another layer: memory lock-in.
If a company's Agent has accumulated over two years a complete task history, the reasons for its decisions, its rejection records, and its business context, and this content resides in a session structure that only that vendor can interpret, then the price for the customer of changing vendors is not exporting a copy of the data, but losing all of the institutional memory.
The strength of this lock-in is higher than that of data lock-in, because it is not portable. A customer list can be exported as a CSV and carried to another CRM for continued use; a segment of context formed by a hundred thousand interactions and bound to a particular session structure is of no use to anyone else once exported.
For buyers, this means that a clause that was previously uncommon needs to be added to contracts: the exportability and interpretability of memory. Not the export of chat records, but the export of a structured task history—the goal, constraints, decisions, grounds for rejection, and result receipt of each task.
For investors, this means a dimension of judgment: are this company's customers staying because the product is good to use, or because the memory cannot be moved. The former is healthy retention; the latter is brittle retention—once a competitor that can import historical memory appears, retention will collapse quickly.
5.5 A Counterintuitive Judgment
A common inference runs: since the Router is the bottleneck, building a better Router is a good business.
This report holds that this inference needs to be discounted. The reason is that the Router's problem is not that it is not good enough, but that it carries responsibilities that should not fall to it. Optimizing a component whose responsibilities are mismatched has a ceiling on its returns; redividing the responsibilities yields structural returns.
The genuinely scarce capability is to land the event log + materialized view structure in Agent scenarios, and to define clearly which things must enter the log and which can be derived. This is inconspicuous, but it is the foundation of every subsequent capability—audit, settlement, attribution, and migration.
6. Structural Flaw Two: No Settlement
6.1 All Five Modules Answer How to Begin
The original article supports four characteristics with five modules. The five modules are: the two-layer architecture, event-driven design, human-oriented interaction, the separation of computation from state and environment, and the Watchdog.
If the problems they are meant to solve are listed out, a very orderly pattern emerges.
The two-layer architecture addresses how to strike a balance between continuity and throughput—that is, how to begin a task and begin many of them at the same time. Event-driven design addresses how to act without waiting for instructions—that is, how to begin proactively. Human-oriented interaction addresses how not to block and how to match the channel—that is, how to make the process of beginning smooth. Compute-storage separation addresses how not to stop because a device goes offline—that is, how to keep what has already begun going. The Watchdog addresses how to recover after an anomaly—that is, how to keep what is continuing from breaking off.
All five answer how to get things running and keep them from stopping.
None of them answers: what the terminal state of a piece of work is, how the resources it occupies are released after the terminal state is reached, and how the terminal state and its cause are recorded.
This absence is not an incidental oversight. It corresponds to an implicit assumption in the original article: a task will end on its own, and once it ends there is nothing further. This assumption holds in short-cycle scenarios with a human watching; it does not hold in long-running, unattended scenarios.
6.2 Five Kinds of Residue
Long-running operation leaves five kinds of things behind, none of which the original article handles.
Zombie task. A task has lost the momentum to advance, yet still occupies context, subscriptions, and budget. It raises no error, because it has not failed; it merely no longer moves forward. In a system with a human watching, such a task will be noticed and shut down manually; in an unattended system, it will remain resident for a long time.
Orphaned subscription. The Worker has ended, but its subscription to a Thread is still attached. Subsequent events continue to pass straight through to a session that no longer exists, and are either discarded or mishandled by a rebuilt session.
Speculative residue. Section 3.4 of the original article introduces speculative execution: the Agent attempts early when it is uncertain whether the result will be adopted—“deliver the result if it has value, discard it if it has no value.” What is discarded is the result, not the process. Those attempts judged to be without value, if they do not enter an explicit archival or deletion process, will keep accumulating in storage and retrieval indexes.
Dangling reference. Chain of recall depends on an ID graph among objects. Any cleanup leaves dangling IDs in the graph, and a recall path breaks as soon as it passes through a dangling ID. The original article does not describe how referential integrity is maintained.
Uncommitted action slot. This item does not yet exist in the original architecture, but if the commit gate is introduced in the manner recommended in Chapter 9 (external actions first enter a staging area and are then committed), the staging area itself will also need a settlement mechanism. An action that has been prepared but neither committed nor cancelled will remain in the staging area indefinitely, and will be mistakenly committed during some retry. Adding a mechanism introduces a new problem; the two must be designed together.
The five kinds of residue share one feature: most do not produce errors but mainly produce cost and uncertainty; orphaned subscriptions and dangling references can additionally cause wrong replies and a break in recall.
6.3 Cost Appears as Efficiency Declining for No Apparent Reason
In this report's view, this is the point most deserving of investor attention.
A defect that produces errors will be caught by monitoring, will enter a fault ticket, and will be fixed. A defect that produces only cost will not. It manifests as a slow rise in the cost per unit of output, and this rise cannot be distinguished from the notion that this architecture is expensive in the first place.
The cost change reported in the original article is this: after removing pass-through, the number of decisions the Router must make rises by about 30%, and total cache-read tokens rise from 23.23 million to 31.77 million, an increase of about 37%. This is an attributable change, because there is a control condition. The cost increase caused by zombie tasks has no such control condition; it is placed in the category of this architecture's operating costs, and no one goes to check.
So the settlement gap appears in the form of efficiency declining for no apparent reason, rather than in the form of failure. The team will think the model has become slower, think the context has become longer, think the vendor has raised prices—anything but that a task that did not end three months ago is still occupying resources.
This feature has a direct implication for investment judgment: if an Agent company has only functional metrics and no capability for cost attribution, its gross margin will deteriorate slowly over a fairly long period, and management will not see the cause until the deterioration becomes obvious. By the time they see it, a large amount of structural waste has usually accumulated.
6.4 The Definition of Settlement and the State Machine
This report defines settlement as a decidable state comprising three conditions: the task enters a terminal state; all four classes of resources occupied by the task are released; and the terminal state and its cause are written to the log.
The four classes of resources are external action slots, subscription relations, context storage, and budget balance.
The corresponding state machine is as follows.
| Current state | May transition to | Transition condition | Must be recorded |
|---|---|---|---|
| Admission | Dispatch, Abandoned | Route determination or manual withdrawal | Admission source, basis of determination |
| Dispatch | Execution, Abandoned | Receipt or rejection by the Worker | Dispatch target, version number |
| Execution | Pending acceptance, Abandoned, Expired | Output completed, budget exhausted, silence timeout | Output identifier, consumption |
| Pending acceptance | Settled, Merged, Abandoned, Expired | Human acceptance, world receipt, manual withdrawal, timeout | Acceptance method, acceptor |
| Settled | Terminal state | — | Result receipt |
| Abandoned | Terminal state | — | Reason for abandonment, grounds for rejection |
| Merged | Terminal state | — | Which task it was merged into |
| Expired | Terminal state | — | Expiration threshold |
The state machine itself is not complex, but it enforces two things that are omitted in the original architecture: every task must have a terminal state; every terminal state must have a cause.
The value of the second is underestimated. The reason a task was abandoned is one of the rarest kinds of knowledge in an organization. What most teams truly lack is not a record of what has been done, but a record of what has been tried and why it did not work. The former can be recalled by semantic similarity; the latter must be matched precisely by condition—because a similar failure will recur only when the conditions are the same.
Making the reason for abandonment a required field of the state machine is equivalent to turning the collection of negative memory into a by-product of the process rather than extra work. This point will be developed further in Chapter 12, later in this report.
6.5 The Settlement Layer Is a Prerequisite for Procurement
For enterprise procurement, the significance of the settlement layer goes beyond saving money.
When an enterprise buys a system, what it buys is not the ability to do work, but the ability to keep accounts. How much did a piece of work cost, who approved it, what was the outcome, and why did it stop—if these four questions cannot be answered, finance cannot place it under any budget line.
This is also why a large number of AI tools remain at the stage of departmental purchase and cannot enter enterprise procurement. It is not that their capability falls short; it is that the accounts cannot be kept clearly. A tool charged per seat can go under the software subscription line; a system charged per task execution, with costs that float with context, must go under the productive expenditure line; and productive expenditure requires that costs be aggregatable, auditable, and comparable.
The settlement layer is precisely the intersection of these three requirements. It turns each task execution into an object that can be booked: it has a beginning, an end, resources consumed, a result, and a responsible party.
From this perspective, settlement is not an engineering optimization item, but a commercialization prerequisite. Whoever builds it first can obtain enterprise budgets; whoever does not can only remain in the position of an internal team tool, sustained by individual payments or departmental funds.
The original article itself mentions this direction. At the end of Section 8.1 it writes that when the operating period lengthens to cross-month or even longer time spans, long-range memory becomes the main bottleneck constraining scalability. This sentence is correct, but it sees only the storage side of memory, not the settlement side. What actually brings a system down after long-term operation is often not a failure to remember, but having remembered too many things that no longer need to be remembered.
7. The Three-Class Acceptance Taxonomy: A Dividing Line for Vertical Agents
7.1 A More Easily Explained Phenomenon
The same Agent architecture runs well in software development scenarios, yet becomes almost unusable when moved to manufacturing sourcing. This phenomenon has been observed repeatedly across the industry, but the explanations are usually wrong.
Common explanations fall into two categories. One says that model capability is insufficient, and that it will be fine once industry models become stronger. The other says that data is insufficient, and that it will be fine once data accumulation reaches the necessary level.
Both explanations avoid a more fundamental question: what happens after the output.
The output of software development is code, and code is immediately followed by compilation, tests, code review, and rollback. When an Agent submits an incorrect change, it is blocked by CI within minutes, or sent back by review. The cost of an error is a few minutes.
The output of manufacturing sourcing is a list of factories. After the list there is nothing. Whether the list is correct is known only after inquiries are sent out, after waiting to see whether the other party replies, whether the quote is appropriate, and whether a factory audit can be passed. This cycle is measured in weeks, even months.
The two may use the same model and the same architecture, yet the results are completely different. The difference is not on the generation side but on the acceptance side.
This report therefore proposes a criterion: what determines whether a vertical Agent can hold up is, first of all, not model capability but acceptance latency.
7.2 The Three Costs of Acceptance
Break acceptance apart, and it contains three costs.
First, the readability cost. Can the output be read through by a person at a reasonable speed? A code change of two hundred lines can be read; a log of a hundred thousand lines cannot be read; a list of three thousand enterprises can be read through, but reading it settles nothing.
Second, the cost of the basis for judgment. After reading it, on what grounds can one say whether it is right or wrong? Some scenarios have an objective basis — a test that passes is a pass, a compilation that fails is a failure; some scenarios have none, only judgments such as that this supplier's quote seems on the high side, and such judgments depend on experience, are unstable, and cannot be standardized.
Third, the feedback-latency cost. Even if it cannot be judged at the moment, how long until the answer is known? Seconds, days, and months correspond to completely different system designs.
Together the three costs determine one thing: how long it takes, and how much human attention it consumes, for an output to go from generation to being confirmed as valid. This duration is what this report calls acceptance latency.
7.3 Class One: Readable and Decidable
The characteristics are: the output is human-readable; right and wrong have an objective basis; acceptance latency is on the order of minutes to hours.
Software engineering is the most typical scenario in this class, and the scenario in this class that has been validated most thoroughly at scale.
The experiments in the original article all fall here. CI messages, code review, pull requests — these are not merely development tools; they are themselves a highly mature piece of acceptance infrastructure. Version control makes every change comparable, diff lets a person look only at the changed parts, tests give right and wrong an objective basis, review gives judgment a second pair of eyes, and rollback keeps the cost of an error controllable.
This infrastructure has accumulated over fifty years.
The success of Agents in software engineering is partly borrowed from this infrastructure. When it submits a change, the diff is generated automatically, the tests run automatically, and review is triggered automatically. It does not need to solve for itself how to let a person judge quickly whether this output is correct, because that problem had already been solved before it appeared.
This point matters for judging the industry landscape. The lead of software engineering Agents does not equal a lead in general Agent capability; it may simply be the first player to find a field where the acceptance infrastructure is already in place. Move to a field without this infrastructure, and the same capability is immediately discounted.
Two further characteristics of class-one scenarios are worth noting. First, the output can be partitioned — a large change can be split into ten small pull requests, each of which can be accepted independently. Second, errors can be isolated — if something is wrong, rollback is enough, and the production environment is unaffected. These two characteristics make class-one scenarios highly tolerant of Agent error, and also keep Agent failures from turning into incidents.
7.4 Class Two: Readable but Undecidable
The characteristics are: the output is human-readable; but right and wrong cannot be determined at the moment and can only wait for the external world to give a receipt; acceptance latency is on the order of days to months.
Manufacturing sourcing is the most typical scenario in this class.
A factory list can be read through by a person. The names, regions, registered capital, main products, and contact details of three thousand enterprises can be read in an afternoon. And after reading? After reading, nothing can be established.
The list says that this company makes auto parts, has registered capital of 50 million yuan, and is located in Changzhou; all of this information is correct. But what procurement really needs to know is three other things: whether it will reply to my inquiry, whether its quote is competitive, and whether it can pass a factory audit. Not one of these three things can be seen from the list.
There is only one way to know: send it out and wait for a reply.
So the acceptance action is split into two segments. The first segment is whether it looks right, which can be completed within a few minutes; the second segment is how things turned out later, which must wait several weeks. The first segment is completed by review; the second can only be completed by a receipt.
Many Agent products stop at the first segment. They generate a handsome list, write ample matching rationale, and hand it to the user. The user looks at it and finds it reasonable, uses it once, discovers that the inquiries sent out draw no response at all, and does not use it a second time.
This is not that the product is poorly made; it is that it has completed only half of acceptance. And the missing half is precisely the part the user actually cares about.
The architectural components class-two scenarios require differ from those of class one.
Class one requires the review layer: organizing the output so that it can be judged quickly, providing diff, providing comparison, providing a chain of evidence.
Class two requires the settlement layer: recording in what form, at what time, and to whom each output was sent; recording how the other party responded, including non-response; distinguishing outputs that were never sent from outputs that were sent but drew no reply.
These two failures look the same but are in fact completely different. The former is a system failure, and delivery must be fixed; the latter is a lead-quality problem, and recall must be fixed. Without distinguishing them, one never knows what to change.
7.5 Class Three: Unreadable
The characteristics are: the output exceeds human effective reading capacity; or the basis for judgment itself does not exist.
This class includes large-scale data cleaning, consistency checking of long documents, and cross-database entity alignment. Agents perform these tasks far faster than people, but after they are done, no one can confirm that they were done correctly.
A typical example is standardizing ten million enterprise records. The Agent finishes running and reports that it processed 9.98 million, leaving 20,000 requiring manual confirmation. These 20,000 cannot be looked through by a person; and how many of the 9.98 million are wrong, no one knows.
The risk in class-three scenarios lies not in efficiency but in unverifiability. The more efficient the system and the more output there is, the less able people are to check it; the probability of error grows while the probability of discovery shrinks.
This class is not suited to fully automatic execution by an Agent; the appropriate approach is sampling plus statistical guarantees. Specifically, set an acceptable defect rate, randomly draw a fixed number of samples for manual checking, and use the hypergeometric distribution to compute the confidence, when all the drawn samples pass, that the defect rate of the whole batch is below a certain threshold.
A concrete algorithm. For a batch of N records with D truly defective, drawing n records, the probability that not a single defective one is drawn is C(N−D, n) / C(N, n). Conversely, if the n drawn records all pass, the probability that the defect rate of the whole batch is above a certain level can be computed. To rule out a defect rate above 1% at 95% confidence, where the total is far larger than the sample, the sample size needs to be about 300 and is largely independent of batch size. This property lets the acceptance cost of class-three scenarios be held at a fixed value rather than growing linearly with the scale of output.
This passage is, in the view of this report, a workable engineering path for class-three scenarios. It does not pursue item-by-item correctness; it pursues holding the density of errors at a known level. For enterprise customers, this commitment is more credible than AI accuracy of 99%, because it can be independently re-checked.
7.6 A Criterion Table
Putting the three classes together.
| Class | Output readability | Basis for judgment | Acceptance latency | Required architectural component | Typical scenarios |
|---|---|---|---|---|---|
| Class one | Readable | Objectively exists | Minutes to hours | Review layer | Software engineering, report generation, format conversion |
| Class two | Readable | Requires external receipt | Days to months | Settlement layer | Manufacturing sourcing, sales leads, recruiting, investment targets |
| Class three | Unreadable | Does not exist or is incomplete | Cannot be determined | Sampling and statistical guarantees | Large-scale data cleaning, cross-database alignment |
This table can be used directly to judge the feasibility of a vertical Agent project. The method is to ask three questions: can a person read the output to the end? After reading, on what grounds can right and wrong be judged? If it cannot be judged, how long until the answer is known?
If the three answers fall in class one, the architectural problem has largely been solved by software engineering, and what the team must do is engineering implementation and scenario adaptation. If they fall in class two, the team must build the settlement layer itself; otherwise the product can only stop at being useful-looking. If they fall in class three, the team must abandon the item-by-item correctness narrative, switch to a statistical commitment, and build the sampling process into the product.
This criterion has far more explanatory power than “our model is stronger.” It explains why, with the same large models, some scenarios can already charge fees while others are still building demos; it also explains why some products that look technically unremarkable make money first — they fall in class one, where acceptance is cheap.
8. The Absence of Measurement: The Budget Line-Item Problem in Enterprise Procurement
8.1 The Four Metrics Reported in the Original Article Are All System-Side
In its experimental section the original article reports four quantities: the p50 and p95 of task completion time, the number of decisions the Router needs to make, the total volume of cache-read tokens, and the batch size together with the time consumed by a single request.
All four quantities are system-side metrics. They can answer how fast the system runs and how much compute it consumes; they cannot answer how much more work people do, and how many fewer mistakes they make, as a result.
For a system designed with people as the starting point, this metric set is incomplete. More troublesome is that with only system-side metrics, any optimization will naturally tilt toward the system side: lower latency and fewer tokens look like progress, even if they leave people more exhausted.
This is not an oversight of the original article alone. The entire Agent industry currently reports this kind of metric: response speed, tool-call success rate, task completion rate. These metrics are useful to engineers and useless to the buyer. The questions the buyer must answer are how many people buying this will save and how much buying this costs per year, and both questions require human-side metrics.
8.2 Eight Metrics Proposed for Addition
Most of the eight metrics in the table below can be computed from the event log, with no additional instrumentation, provided that the log fields are fixed at the architecture design stage; M1 relies on manual sampling and M4 requires recording the time people spend in the system, so these two need separate data sources.
| No. | Metric | Definition | Calculation | Use |
|---|---|---|---|---|
| M1 | Routing accuracy | The share of events dispatched to the correct Worker | Manual sampling of 1%, with a misrouted or unnecessary dispatch counted as an error | To judge whether the Router is reliable |
| M2 | Pass-through hit rate | The share of all events that pass through via subscription | Number of pass-through events ÷ total number of events | To measure the Router's load structure |
| M3 | Tokens per accepted output | Token consumption per unit of accepted output | Total tokens in the interval ÷ number of accepted outputs | The primary metric of cost efficiency |
| M4 | Human minutes per accepted output | Human time consumed per unit of accepted output | Human minutes invested in the interval ÷ number of accepted outputs | Directly corresponds to the headcount budget |
| M5 | First-pass acceptance rate | The share of outputs that pass acceptance on first submission | Number of first-pass outputs ÷ total number of submissions | To measure output quality |
| M6 | Settlement rate | The share of tasks that reach a terminal state, release resources, and have a reason recorded | Number of settled tasks ÷ total number of tasks | To measure the settlement gap |
| M7 | Duplicate-intake rate | The share of intents accepted more than once | Number of duplicate intakes ÷ total number of tasks | To measure deduplication capability |
| M8 | Rework rate | The share of outputs overturned and redone after acceptance | Number of overturns and redos ÷ number of accepted outputs | To measure hidden cost |
A note on numbering: in this report M5 and M6 are the first-pass acceptance rate and the settlement rate; in this institute's earlier report, “Super-agent Architecture: An Independent Recomputation,” the two metrics bearing the same numbers are the speculative hit-and-waste rate and the share of zombie tasks. M1 to M4 and M8 mean the same thing in both reports.
M3 and M4 are the two most important in this table. M3 attributes cost to accepted output, and its denominator is not tasks; this point is crucial: the original reports a single-experiment token total with no task-level granularity at all, while a large number of tasks produce no output and receive no acceptance. M4 corresponds directly to the attention discussed in P1: if this metric does not improve, then no matter how the architecture is designed, the narrative about attention has not been validated.
M6 and M7 correspond to two hidden gaps. Most systems do not do too little; they do too much that should not be done and leave too much unsettled. Only a system that can state clearly the share of its own zombie tasks is qualified to talk about long-term operation.
8.3 M3 and M4 Determine Whether It Enters the Budget
For the buyer, the significance of M3 and M4 is not greater precision but whether the accounts can be done.
Enterprise budget line items are layered. Software subscriptions are counted by seat, marketing expenses by project, productive expenditure by unit of output. If an Agent system can report only how many tokens per month, the buyer cannot put it into any existing line item and can only open a new one, AI experiment fee, and the quota for that line item is usually very small and must be re-applied for every year.
Once it can report how much is consumed per valid lead obtained, or how many human minutes are consumed per submittable quotation completed, the nature of the thing changes. It can be placed into customer acquisition cost, it can be placed into workforce-efficiency metrics, and it can be compared horizontally with other options. At this point the object of the procurement discussion shifts from whether to try it to whether it pays off, and the latter is a question that can be signed.
This is also why this report holds that M3 and M4 should be treated as product capability rather than as operational reporting. A company that can report these two numbers is not selling a tool but capacity.
8.4 Metrics Will Be Gamed, So They Must Be Paired
Any single metric will be optimized until it is distorted.
If only M3 is assessed, the system will tend to pick tasks that are easy to accept and push the hard ones to people. If only M1 is assessed, the Router will tend to hand all events to people, because that way it cannot misroute. If only M6 is assessed, the reclaimer will terminate tasks too early, terminating tasks that could have been completed. If only M8 is assessed, the system will tend to produce the most conservative plan.
It is therefore recommended to assess them in pairs: pair M3 with M8, to prevent sacrificing quality to save cost; pair M1 with M2, to prevent the Router from degenerating into a forwarder; pair M6 with M5, to prevent settling for the sake of settling.
This kind of pairing is nothing new; it is standard practice in performance measurement. The reason to spell it out here is the particularity of Agent systems: their execution speed is far faster than human checking speed, and once metrics are gamed, the deviation accumulates to a large magnitude in a very short time.
For investors, this judgment can become a due diligence question: which metrics do you assess, and how do you prevent them from being optimized into distortion? A team that can answer with pairing logic usually has real observation of its own system; one that cannot answer is most likely not yet running at a scale that needs worrying about.
9. Security, Accountability and the Procurement Threshold
9.1 The Scope the Original Article Sets for Itself
Section 8.4 of the original article discusses security and privacy in a very short passage, and explicitly acknowledges: “If there is no way to solve the security and privacy problems well, then the Super-agent can only work within a very small and trusted scope.”
This statement is accurate, and more serious than it appears. It is not saying that security needs to be strengthened, but that the boundary of applicability is determined by security. A system that can work only in a small, trusted environment means that it cannot be delivered as an external service.
The original article gives two concrete risks. First, the cloud-side Agent Loop is continuously connected to external events while the device side stores private code and local credentials; once this cross-device link is breached, all edge devices face the risk of being taken over. Second, even if the cloud side is not breached, as long as device-side credentials enter the model context, there is a leakage risk during normal execution.
Neither of these can be solved by strengthening the prompts. They are structural problems: the system must hold a large amount of high-privilege capability while being exposed to a large amount of untrusted input. When these two conditions hold at the same time, the risk is not a matter of probability but of time.
9.2 The Check Is Placed in the Wrong Position
The event-filtering design in the original article is reasonable in itself: a fast admission check at the program layer, judgment at the semantic layer. But what it solves is the noise problem, not the security problem.
Filtering reduces the volume of noise, not the attack success rate.
An example the original article gives illustrates the point well: the Agent continuously follows public group chats and, without anyone @-mentioning it, proactively identifies defects and submits a fix Pull Request. Within an internal trusted group this behavior is reasonable, and highly efficient. But the same behavior placed in a group open to the outside amounts to turning anyone posting a single sentence into a trigger for a Worker holding full tool permissions.
The filtering mechanism cannot help here. Because the message the attacker sends looks, by content, like an ordinary defect report — it will even be written very properly, because its whole purpose is to pass the filter.
The correct position for the security boundary is before the outward action, not at the moment the event enters. This is the end-to-end principle in security engineering: a check placed at a position where information is insufficient is either redundant or wrong. The information needed to judge whether this action should be taken lives on the policy side — action type, target scope, current budget, historical frequency — not on the event side. The event side knows only what one sentence looks like.
This leads to a primitive that this report proposes: the commit gate.
The specific approach is to split actions that cross the sandbox boundary into two stages. The first stage is staging: the Agent generates an action, writes it to the staging area, and does not execute it. The second stage is commit: actions in the staging area are actually executed only after passing policy-gate validation. The policy gate validates on the basis of the action's type, target scope, budget and frequency; it does not validate whether this sentence looks like a request.
The advantage of this design is that it turns judgment from a probabilistic problem into a rule-based problem. Rules can be audited, can be tested, and can be reproduced after an incident. Model judgment of whether this message is trustworthy cannot do these three things.
At the same time, the commit gate brings a new engineering problem, already mentioned in Chapter 6 above: the staging area itself needs a settlement mechanism. An action that is ready, neither committed nor cancelled, will remain in the staging area indefinitely and be mistakenly committed during some retry. Adding a mechanism introduces a new problem, which is also why the settlement module must be designed together with the commit gate.
9.3 The Attributable Subject
The original article does not discuss accountability attribution. This is not an oversight but a consequence of the scenario: inside a team, accountability is naturally resolved by organizational relationships. Whoever committed the code is the one to ask; whoever posted the reply in the group is the one to ask. Organizational relationships are themselves the chain of responsibility.
Once this system enters enterprise procurement or external service, accountability attribution becomes a precondition.
An enterprise cannot procure a system in which no one can be found when something goes wrong. This is not only a legal issue but also a process issue: any outward action requires a subject that can be called to account.
This report therefore proposes making the attributable subject a first-class architectural constraint: every action that crosses the sandbox boundary must be bound in the log to a responsible subject. This subject can be a natural person, or it can be a registered service identity, but it cannot be the system.
This constraint looks like it merely adds a field, but in practice it changes the system design. It requires that every action be traceable to the task that initiated it, the policy that approved it, and the person responsible for that policy. This in turn requires that the log be complete, append-only and tamper-proof — that is, the structure proposed in Chapter 5.
At this point it can be seen that the recommendations of the preceding chapters interlock: the log sequence number solves the reconstructability of memory, settlement solves the attributability of cost, the commit gate solves the interceptability of actions, and the attributable subject solves the traceability of responsibility. The four things share the same infrastructure.
9.4 The Three Preconditions for Enterprise Procurement
Combining this chapter with the preceding ones, three preconditions for enterprise procurement can be summarized. Of the three hurdles set out in Chapter 2, settlement and attributability become two concrete conditions here; the third condition appears only at the procurement stage.
Settleable. Every execution can be attributed to an output, with consumption, result and unit price. This is supported jointly by the settlement layer and the two metrics M3 and M4.
Attributable. Every outward action can be traced to a responsible subject, with authorization, record and boundary. This is supported jointly by the commit gate and the attributable-subject constraint.
Exitable. When a customer leaves, it can take away the complete task history and decision rationale, and this content remains readable in the new system. This is supported by the log structure.
Of the three conditions, the third is the easiest to overlook, but it often determines whether a customer dares to use the system deeply. If a customer knows that the deeper it uses the system, the harder it is to leave, it will at some point voluntarily stop going deeper — this point usually appears when the system begins to carry critical processes. This is a self-imposed growth ceiling that is invisible from the outside and discoverable only by asking the customer.
10. Where the Value Pool Migrates
10.1 A Three-Layer Structure
To discuss the distribution of value in the Agent industry, the chain can first be split into three layers.
Model layer. It provides reasoning capability. This layer is characterized by rapid capability convergence, rapid price decline and strong economies of scale. Over the past two years, the price of models at the same capability tier has fallen by more than an order of magnitude. The competitive landscape at this layer is already fairly clear: a few players hold most of the share, and the rest survive on verticalization or cost.
Scheduling layer. That is, the harness and architecture the original article discusses. It is responsible for organizing model capability into a system that can run continuously: routing, context management, event handling, state recovery. The entry barrier at this layer is not high, but doing it well is not easy — it requires handling a large number of edge cases, being sensitive to cost, and polishing in long-tail scenarios.
Scenario layer. The task definition, data, acceptance criteria and delivery method of a specific industry. This layer is highly fragmented; every vertical has to be redone once, but once it is done, the replacement cost is high.
The original article's contribution lies mainly in the second layer. It articulates one form of the scheduling layer and gives an implementable path. This also means that competition around the second layer will quickly become crowded.
10.2 Four Possible Value Capture Points
On a chain that is converging rapidly, value concentrates where replication is difficult. This report holds that there are four possible positions.
The first is a reasoning cost advantage. Whoever can push unit reasoning cost lower at equal quality gains an extra slice of gross margin in every scenario. This is a pure scale and engineering advantage, independent of scenario, and winner-takes-all. The opportunity at this layer belongs to players with in-house R&D capability or special hardware conditions, not to the application layer.
The second is scheduling engineering quality. With the same architecture, one team can achieve stable operation, controllable cost and recoverable failure, and another team cannot. This gap really exists, but its moat is shallow — it depends on accumulated experience, and experience spreads as talent moves. This layer can support a good company, but cannot support a high valuation.
The third is acceptance facts. This is the position this report considers the most valuable.
Acceptance in the second class of scenarios depends on external receipts: whether the customer replied, whether the quote was appropriate, whether the factory audit was passed, whether the order was won. These facts are not in the model, not in public data, only in the real business flow. Whoever can accumulate such facts lawfully holds the basis for judging which lead is worth sending out.
The characteristic of such facts is: the more they are used, the more there are; the more there are, the more accurate they become; the more accurate, the harder they are to replace. They are one of the few kinds of asset that strengthen themselves over time.
The fourth is assumption of responsibility. When Agents begin to perform outward actions on behalf of people, someone needs to bear responsibility for those actions. Assumption of responsibility can take the form of compliance qualifications, insurance products, audit services, or an explicit service identity. This layer is currently almost blank, but as the actions Agents undertake grow heavier, it will change from an option into a necessity.
Among the four positions, the first requires capital, the second requires time, the third requires scenario and patience, and the fourth requires qualifications and trust. For most entrepreneurs, the third is the more realistic entry point; for investors, the third is the position with a compounding effect.
10.3 Three Observation Windows
To judge whether this migration has actually happened, three windows can be watched.
Window one: the keywords in public discussion. If discussion shifts from how many modules the architecture has to how much one unit of output costs, it indicates that competition at the scheduling layer has entered the cost stage and that value has begun to shift downstream. This shift usually occurs after the capability gap narrows, lagging technical maturity by about one to two quarters.
Window two: changes in pricing. If offers such as billing by valid lead or billing by accepted output begin to appear on the market, it indicates that metrics such as M3 and M4 have entered commercial practice. This is the sign that the second class of scenarios has truly begun to commercialize, and also the sign that the settlement layer has been implemented. At present the mainstream pricing method is still per seat or per call volume, which indicates that the industry is still stuck at the first layer.
Window three: the emergence of memory migration tools. If tools or standards appear that can import, export and convert Agent task histories, it indicates that customers have begun to vote with their feet and that vendor lock-in is being broken. The earlier this window appears, the more fully competitive the market is; the later it appears, the stronger the lock-in of existing players, but it also indicates that the ceiling of this market is limited by customer trust.
None of the three windows requires internal data; they can be observed from public information and product pages.
10.4 Four Directions Not Worth Investing In
Conversely, four directions that this report considers not worth investing in can also be listed.
Those that only optimize the Router. The Router's first problem is performance, which Chapter 3 quantifies; its second is a mismatch of responsibility, which Chapter 5 establishes. Optimizing only a component whose responsibility is mismatched has a capped return, and can be zeroed at any time by a single structural redesign.
Those that only do prompt orchestration. The recalculation in Chapter 4 shows that the most effective variable in the original article's experiment may have been the removal of the model's discretion, and the implementation cost of this point is extremely low. Any differentiation formed solely by prompts and workflow orchestration will be copied quickly, and will be swallowed by the built-in capabilities of the next generation of models.
Those that claim to be general but whose scenario falls in the third class. A product that claims it can do anything usually means it has not chosen an acceptance method. If its actual scenario falls in the unreadable class, then its accuracy cannot be verified, and the customer will not use it a second time. The growth curve of such products usually looks good; the retention curve looks bad.
Those that rely on memory lock-in for retention. Chapter 5 above analyzed that the retention brought by memory lock-in is brittle retention. It makes short-term data look good, masks insufficient product strength, and collapses in a concentrated way when a competitor offers migration tools. For investors, this is a metric that needs to be actively identified and discounted.
10.5 An Overall Judgment
Compressing this chapter into one sentence: in this round of generational change in Agent architecture, the truly scarce resource is not generation capability, but the facts required for acceptance and the qualification to bear responsibility.
The cost of generation capability is still falling rapidly, and anyone can buy it; acceptance capability is constrained by human judgment and organizational authorization, and will not expand in step as models become stronger; and the qualification to bear responsibility requires time, qualifications and trust, and is the hardest part of this chain to accelerate.
This judgment has a somewhat counterintuitive corollary: in this industry, the team that can explain clearly how it knows it did the right thing is more likely to last than the fastest team.
The reason the original article's experiment is persuasive is precisely that it gives a quantity that can be tested — task completion time. Even if this quantity does not measure what it intends to prove, it is at least explicit, reproducible and open to challenge by others. By contrast, much of the industry's narrative about Agent capability does not even have a single falsifiable quantity.
This is also why this report is willing to spend a large amount of space on recalculation. Recalculation serves to demonstrate a way of judging that can be inherited: split a claim into propositions, match the propositions to the data, compute the data into a conclusion, and then check whether the conclusion and the claim are the same thing.
This method is not new, but at a stage where conceptual density far exceeds evidence density, it is more useful than any prediction.
11. Twelve Questions for Investors
The judgments of the preceding chapters can be compressed into a single question-and-answer checklist. The twelve questions below are arranged in three groups — technology, business and governance — and each question is followed by what counts as a passing answer and what should raise caution.
11.1 Technology
| No. | Question | A passing answer | An answer that warrants caution |
|---|---|---|---|
| Q1 | Have you tested forced delegation or an equivalent minimal scheme? | Yes; it performed X% worse, so we chose Y | No, but our architecture is clearly more complex and more complete |
| Q2 | When you report a performance improvement, what is the dependent variable? | Human throughput, defined as accepted output completed per unit of human time | Task completion time, response latency |
| Q3 | What is the token consumption per unit of accepted output? | The number exists, and context cost can be separated from execution cost | Only total call volume or the monthly bill is reported |
| Q4 | Can the event log replay the complete history of a task? | Yes; the log is append-only and can be replayed by sequence number | The chat record can be read, but the decision process is not stored in structured form |
| Q5 | After a task reaches a terminal state, how are the resources it occupies released? | There is a state machine, a reclaimer and a budget cap | The task ends when it is completed, and exceptions are handled manually |
| Q6 | Where does memory live, and can it be migrated? | The log is authoritative; memory is a materialized view that can be rebuilt | Memory lives in the session context, and the export is text only |
Q1 and Q2 are direct corollaries of Chapter 4. Q1 tests whether the team has run an ablation; Q2 tests whether it realizes that latency and throughput are not the same thing.
Q3 tests whether cost can be attributed to output. Q4 and Q6 test the structure of memory. This group is the one most easily skipped in due diligence, because it sounds like an engineering detail while in fact it is the core of valuation — whether memory can be migrated determines whether customer retention is healthy or brittle.
Q5 tests the settlement gap described in Chapter 6. A system without a reclaimer is two different things when it has run for three months and when it has run for three years.
11.2 Business
| No. | Question | A passing answer | An answer that warrants caution |
|---|---|---|---|
| Q7 | Which class of acceptance does your scenario fall into? | It states clearly that it is class one or class two, and gives the reason | It says every scenario can be handled |
| Q8 | After the customer has used it, how do you know it got it right? | There is receipt data, and the distributions of what was sent, what was answered and what resulted can be stated | Customer feedback is very good and NPS is high |
| Q9 | What is the pricing unit? | Per accepted output, per qualified lead, per completed workflow | Per seat, per token, per number of calls |
| Q10 | Why do customers stay? | Because the output is effective, and the switching cost lies in data and process | Because their historical records cannot be moved |
Q7 is a direct application of Chapter 7. This is the question that best separates having a scenario from having a narrative — a team with a scenario will immediately say how long its acceptance latency is; a team without one will say the technology can adapt.
Q8 tests whether the settlement layer has actually landed. NPS is a subjective rating; a distribution of receipts is objective fact, and only the latter can support product iteration.
Taken together, Q9 and Q10 show whether the company is selling capacity or selling a tool. A company selling capacity has unit economics; a company selling a tool has only subscription revenue.
11.3 Governance
| No. | Question | A passing answer | An answer that warrants caution |
|---|---|---|---|
| Q11 | Where are actions that cross the sandbox boundary intercepted? | At the policy gate, validated by action type and scope | Constrained in the prompt and filtered at the event entry point |
| Q12 | When an incident occurs, who is the responsible party? | Every outbound action is bound to a natural person or a service identity | The system executes automatically, and the customer judges for itself |
Q11 tests the end-to-end principle of Chapter 9. Putting the check at the event entry point is a common mistake: it looks like security work, but in practice it is only noise reduction.
At present, few companies can give a complete answer to Q12. But as long as a company intends to serve enterprise customers, procurement will ask this question sooner or later. Teams that think it through in advance will gain a real period of time advantage in the enterprise market.
11.4 How to Use This Checklist
The twelve questions do not all need to be asked. In actual due diligence, four questions — Q1, Q3, Q7 and Q9 — can sort most projects into tiers within half an hour. The remaining eight can be added during technical due diligence.
It is worth emphasizing that the purpose of this checklist is not to screen projects out but to price them. If a team has not run a control at Q1, that does not mean it cannot build a good product; it only means its technical advantage has not yet been proved, and the valuation should not include that premium.
12. The Manufacturing Landing Point: From Found to Verified
12.1 Why Manufacturing Sourcing Is Class Two
The task structure of manufacturing sourcing corresponds exactly to class two in Chapter 7.
The output is a list of factories, and a person can read through it. The cost of readability is not high. The basis for judging lies outside the list — whether this factory will reply, whether its quotation is competitive, whether it can pass a factory audit. Feedback latency is measured in weeks.
This means the core capability of a sourcing agent lies not in recall but in settlement.
Recall is no longer scarce. Tianxia Gongchang's factory records cover 4.8 million Chinese manufacturing enterprises, 1,965 industry sub-categories and more than 1,000 industrial belts; of these, 1.8 million factories have foreign-trade business and more than 3 million factories carry direct decision-maker contact details. These numbers show that, within this library, being able to find something at all is no longer the bottleneck.
What is genuinely scarce is finding the right one — or, more precisely, finding one that a receipt has verified.
What a buyer wants is not three thousand factories that meet the criteria but twenty factories that will answer its messages, quote within budget and pass a factory audit. Between three thousand and twenty stands not a smarter retrieval but a receipt.
12.2 What the Data Show
If our coverage data are broken down by the three classes of Chapter 7, an interesting conclusion follows.
At the layer of readability, supply is already sufficient. Company name, region, registered capital, years since establishment, main products, business scope and contact details — these fields make up the bulk of a list, and they are also the entire content that most sourcing products deliver.
At the layer of the basis for judging, supply is fractured. Deciding whether a factory is worth contacting requires information that includes: whether it has recently taken orders of the same kind, whether its capacity is saturated, what its quoting habits are, and which type of customer it prefers to respond to. This information is not in business registration data, nor on the company website; it exists only in actual inquiry exchanges.
At the layer of feedback latency, there is currently almost no productization. What happens after an inquiry is sent is not recorded by most systems. How many were sent, how many were answered, why there was no answer, and how far the conversation went after an answer — these data are scattered across salespeople's WeChat, email and memory.
The imbalance among these three layers of supply determines where the product focus of this industry should shift.
12.3 Three Actionable Recommendations
Based on the judgments above, this report offers three recommendations, addressed to teams building manufacturing sourcing products.
First, make the receipt a first-class datum.
The concrete approach is this: every outbound contact records three fields — the channel of contact (phone, WeChat, email, platform message), the time of contact, and the counterpart's response (including no response). No response must also be recorded, and it is the most important kind of record, because it distinguishes two entirely different failures: nothing was sent out, and something was sent out but nothing came back.
Once these three fields are complete, the definition of acceptance changes: from a person clicking approve to the world returning a receipt. This change looks as if it only adds a few columns of data; in fact it pulls the product from class one to class two, and gives the product, for the first time, the capacity to accumulate compound interest.
Second, take verified rather than matched as the delivery standard.
Most sourcing products open their report with a formulation along the lines of “we found N factories that meet your criteria”. The problem with this standard is that the larger N is, the less the customer knows where to start, and N bears no relation to a closed deal.
A more deliverable standard is, for example: “Of this batch of 200, 86 have been contacted, 31 have responded, 12 have moved to the quotation stage and 3 have completed a factory audit.” Each of these numbers can be checked by the customer, and each points to the next action.
This shift in standard has a side effect: it forces the product to handle contact, not just retrieval. That is exactly the shape a class-two scenario should have.
Third, build negative memory.
The knowledge that is genuinely scarce in a team is often not what it has done but what it has tried and why that did not work. In sourcing, this appears as: a certain type of enterprise in a certain region does not answer inquiries, factories of a certain size do not accept small-batch orders, a certain industry has its capacity fully booked in a certain season.
The retrieval semantics of this kind of knowledge differ from those of positive memory. Positive memory can be recalled by similarity; negative memory must be matched exactly by condition, because a similar failure recurs only when the conditions are the same. It therefore cannot be stuffed into a semantic search; it needs structured condition fields.
The value of this rises over time. A company that has done sourcing for three years, if it has completely recorded the conditions of every failure, possesses something that others cannot obtain by purchasing data. This cannot be replaced by model capability, nor bought quickly with capital.
12.4 A Larger Judgment
Manufacturing is a good proving ground for agent quality because it has three characteristics at once: the tasks are complex enough, acceptance is expensive enough, and customers are pragmatic enough.
Complex tasks mean model capability has room to matter; expensive acceptance means the settlement layer has real value; pragmatic customers mean conceptual narratives win no orders.
Together these three characteristics will force out a generation of products that can genuinely run the numbers. They will not talk about autonomous agents; they will only talk about how many of this batch of leads have been verified. Their technical sophistication may be lower than that of general-purpose agent companies, but the problems they solve are real.
To the third question posed at the beginning of this report — in which scenarios this architecture holds — manufacturing gives the answer: it can hold in manufacturing, but only if the settlement layer is put in place; the original configuration holds only in class one. Software engineering relies on the review layer; manufacturing relies on the settlement layer. Both forms belong to the broad direction of continuous presence, but they require completely different engineering capabilities.
Conflating these two forms is the most common judgment error in the industry today.
13. Items Still to Be Verified
The items below could not be closed at the time this report was written; they are listed for later checking. This report has not substituted computed values for these gaps in the main text.
- Section 7.2 of the original does not define the measurement basis of two metrics: per-request latency and inference time apportioned to a single decision. The two are not equal at a batch size of 1 (2.5 seconds versus 6.4 seconds) and cannot be explained by the same service time. This report's recomputation of utilization treats per-request latency as the duration of one LLM call; if the basis differs, the result will change.
- The original does not disclose the model type, parameter count and context length used by the Router and the Worker respectively, so the judgment on unit cost in Chapter 3 can only remain at the order-of-magnitude level and cannot be converted into an amount of money.
- The original gives no token pricing; this report uses only token volumes and ratios and does not convert them into money.
- The original states that “a person can usually only follow 3 to 5 active sessions at once”, without citing a source or explaining the measurement method. This report treats it as an empirical value with no stated source, and notes that it may correspond to three different mechanisms (working-memory capacity, interruption-recovery cost, the capacity to bear consequences), whose architectural implications differ.
- In the original experiment, work requests account for 6.7% of the 300 messages, and no real-world basis for that proportion is given. The conversion of unit cost in Chapters 3 and 5 depends on this proportion.
- This report has not obtained the code of the prototype repository dsh-superagent-prototype; the recommendations in Chapter 6 regarding the settlement layer and in Chapter 9 regarding the commit gate are design inferences, not descriptions of an implementation.
- Catalini, Hui and Wu divide work into four categories; this report has not compared, item by item, their classification with the three classes of acceptance scenarios in this report, and the relationship between the two awaits dedicated discussion.
14. Method and Literature
14.1 What This Report Did
The work of this report can be summarized in three steps.
The first step is decomposition. The argument of the original is broken into seven propositions that can be judged true or false, and evidence grades are marked at the key points. The purpose of this step is to give later discussion a common object — without decomposition, both criticism and defense miss their target.
The second step is recomputation. The data published in the original are recalculated to derive the relationship among utilization, batch size and natural arrival volume, and to check whether the experiment's dependent variable is consistent with its claim. The value of recomputation is that readers can verify it independently, without relying on the narrator's credibility.
The third step is extrapolation. Technical conclusions are translated into industry and investment judgments, and each extrapolation is tagged with the assumptions it depends on. Wherever an assumption lacks support, the item goes onto the list of items still to be verified rather than being concluded in the main text.
Beyond these three steps, this report makes no forecast. The reason is simple: this industry changes faster than any forecasting model is updated, so a number for three years from now is worth less than a criterion that can be used today.
14.2 Primary Material
- DeepSeek Harness team: “Super-agent Design Exploration: Toward a More Autonomous Agent System” (“Super-agent 设计探索:迈向更自主的 Agent 系统”), 31 October 2026. All E1 and E2 material in this report comes from this article.
- Contemporaneous media accounts: IT之家, 驱动中国, 观点网, 读懂AI时代, 同花顺 and others, 31 October 2026. Used to gauge the distribution of public discussion; not used as technical evidence.
14.3 Secondary Literature
- Anthropic: Scaling Managed Agents: Decoupling the brain from the hands, April 2026. Cited in Section 5.2 of the original; referred to in Chapter 5 of this report in the discussion of statelessness.
- Catalini, C., Hui, X., Wu, K.: Some Simple Economics of AGI, arXiv:2602.20946. Source of the discussion of the verification bandwidth and measurability gap.
- Saltzer, J. H., Reed, D. P., Clark, D. D.: End-to-End Arguments in System Design, 1984. The basis for the argument on the placement of checks in Chapter 9.
- Saltzer, J. H., Schroeder, M. D.: The Protection of Information in Computer Systems, 1975. The principles of least privilege and complete mediation.
- Kung, H. T., Robinson, J. T.: On Optimistic Methods for Concurrency Control, 1981. Source of the analogy of the sequence point and the commit boundary in Chapter 5.
- Denning, P. J.: The Working Set Model for Program Behavior, 1968. Source of the working set concept in Chapter 5.
All secondary literature above was retrieved on 31 October 2026. This report cites only their conclusions and does not restate their derivations.
14.4 Division of Labor with the Institute's Previous Paper
In the same month, this institute published “Recomputing the Super-agent Architecture” (“Super-agent 架构的独立复算”). That report dealt with what the original says and what the data support; this report deals with what those conclusions mean for the industry.
The two reach the same conclusions but address different readers. The former is for engineers and researchers and provides formulas, data and reproducible derivations; this paper is for analysts and investors and provides criteria, structures and an actionable question list.
When the original data need to be checked, go back to the former. When a judgment needs to be made, this paper can be used directly.
14.5 A Closing Note
This report's criticism of the original does not amount to a denial of the DeepSeek Harness team's work. On the contrary, it is precisely because it published three numbers — arrival rate, batch size and request latency — that this report's recomputation became possible. In the current environment of technical communication, teams willing to hand over data that can be tested are few.
The value of criticism is to arrange inheritable material into a form that can be safely inherited. This architecture description will be implemented by many teams; the work of this report is, before it is inherited, to check the parts that can be checked and to mark the parts that cannot be generalized.
That is what industry research should do.